An AI writing service is unavailable. The editorial calendar is still full, a campaign launch is approaching, and your team is unsure whether to wait, switch tools, or start drafting by hand. The outage is a technical event; the disruption to publishing is an operating-model problem. Resilient content teams decide in advance which work can pause, what must continue, and how quality and accountability stay intact when a dependency fails.
Resilience does not mean buying duplicate capacity for every tool or promising uninterrupted AI output. It means preserving the most important editorial outcomes at an acceptable level of quality and cost. The NIST Generative AI Profile addresses contingency processes for failures in third-party AI systems, including identifying fallback options and testing them. Marketing teams can apply that principle proportionately to their publishing workflows.
Map the workflow before choosing a fallback
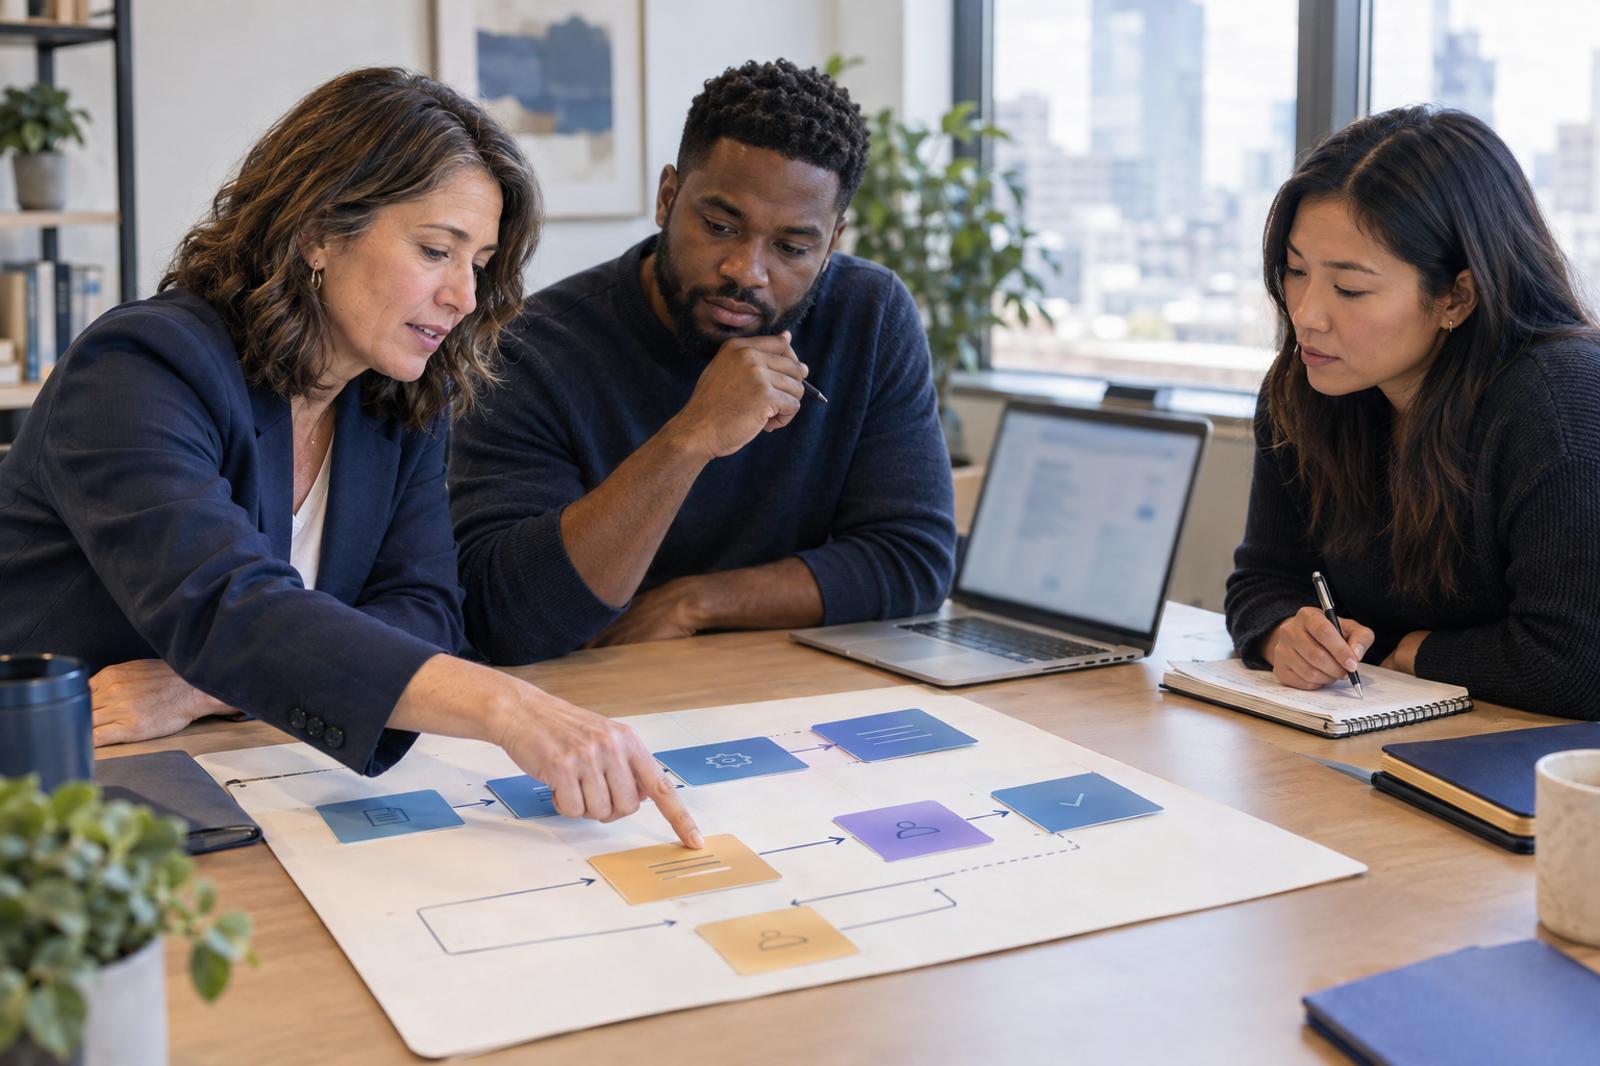
Start by mapping the path from request to published asset: intake, research, drafting, source verification, review, CMS entry, and distribution. At each step, record the external services, data, people, and permissions it depends on. A single workflow may rely on a model provider, an orchestration layer, a source database, a brand-approval tool, and a publishing system; a model outage is only one possible break point.
Then classify work by business impact rather than by how much AI it uses. Mark deadlines and consequences: a regulated product claim, an urgent service update, and an evergreen article refresh should not share the same recovery priority. For each class, decide what can wait, what can proceed with reduced scope, and what must stop until an authorized reviewer is available. A simple impact scale—critical, time-sensitive, and deferrable—is often enough to guide action.
Set realistic recovery targets
Choose a recovery-time objective (RTO): the longest acceptable delay before the affected editorial function is restored. Also define a recovery-point objective (RPO): how much recent work the team can afford to lose or recreate. For a queued batch of evergreen outlines, a longer RTO may be acceptable; for a public correction or launch-day announcement, the target may be much shorter. These are business decisions, not promises that a vendor will meet a particular uptime level.
Keep targets tied to the audience and publishing obligation. If the work can be rescheduled without material harm, queue it rather than paying for a complex always-on backup. If delay creates customer, compliance, or revenue risk, assign an accountable owner and a tested path that does not depend on the unavailable service.
Build a fallback ladder, not a single replacement
Document a small set of safe operating modes. A practical ladder might be: continue unaffected work; queue tasks that need the unavailable service; degrade to a narrower format or simpler workflow; switch to an approved alternate model for low-risk tasks; and operate manually for critical items. Each step should state who can activate it, what work qualifies, and what checks remain mandatory.
For example, a team could continue editing already-drafted work, pause new long-form first drafts, and use a human subject-matter expert for a time-sensitive customer update. An alternate model may be appropriate only if it has passed the same task-specific quality checks and meets data-handling requirements. Do not silently route content to an unapproved model, weaken source requirements, or skip human review simply to keep output volume unchanged.
This is the editorial equivalent of graceful degradation: preserve useful service at reduced capability instead of treating anything short of full operation as total failure. In a content operation, that might mean fewer drafts, shorter formats, or a temporary shift toward review and distribution work while generation is paused.
Make quality and provenance non-negotiable
Every fallback needs explicit guardrails. Keep the same rules for factual claims, source attribution, privacy, rights, brand voice, and final approval. If a fallback changes the model, prompt, retrieval source, or human role, record that change with the asset. Label queued drafts and partially completed jobs so they cannot be mistaken for reviewed work. A continuity plan that restores throughput but loses provenance or creates unreviewed claims has transferred the outage into a quality incident.
Define a clear stop condition too. If the team cannot verify a material claim, preserve source links, or secure the required approver, the safe fallback is to delay or withdraw the asset. The objective is continuity of trusted publishing—not publication at any cost.
Assign incident roles and signals
Name one incident lead who can declare a workflow degraded, set priorities, and communicate status. Identify a technical contact for vendor and integration issues, an editorial lead for work triage, and an approver for any change in model or review policy. Smaller teams can combine these roles, but the responsibilities should still be explicit. Prepare a short status message for writers, reviewers, stakeholders, and, when needed, audiences.
Monitor practical signals: provider error and latency rates, failed or stuck jobs, queue age, number of assets awaiting human review, and missed publishing deadlines. Connect these signals to thresholds that prompt a decision—for example, pause retries after repeated failures, move eligible work to the queue, or notify the incident lead. Unbounded retries can make an outage worse; the Google SRE guidance on cascading failures explains why retry limits and backoff matter in dependent services.
Rehearse the plan with a real scenario
Run a short tabletop exercise before a high-stakes campaign or at a regular operating review. Pick one scenario—provider outage, rate limiting, lost connection to a source library, or an unavailable reviewer—and walk through who declares the incident, which work continues, what gets queued, and what quality checks remain. Test the actual fallback rather than merely reviewing the document. Confirm that people can find the approved prompts, source materials, templates, and contact details without relying on the affected tool.
After the exercise or a real incident, record what happened, how long the critical workflow was impaired, how much work had to be recreated, and whether any content-quality controls were bypassed. Update the dependency map, thresholds, or fallback instructions based on evidence. The goal is not a perfect plan; it is a plan that gets more reliable each time it is used.
A practical continuity checklist
- Map critical editorial steps and their third-party dependencies.
- Classify content by impact, deadline, and acceptable delay.
- Set an RTO and RPO for high-priority workflows.
- Define queue, reduced-scope, approved-alternate, and manual modes.
- Keep fact-checking, rights, privacy, provenance, and approval requirements intact in every mode.
- Name an incident lead and the owners of editorial, technical, and approval decisions.
- Monitor failures, queue age, and review backlog; cap retries to avoid compounding problems.
- Rehearse one failure scenario and update the playbook from lessons learned.
For a related framework on deciding which steps should be automated and where human judgment must remain in control, see AI Content Workflows: Where Automation Helps and Where Humans Must Lead. A resilient workflow makes those boundaries visible before a disruption, so the team can keep serving its audience without improvising its standards under pressure.